AEOsim blog
Highlights
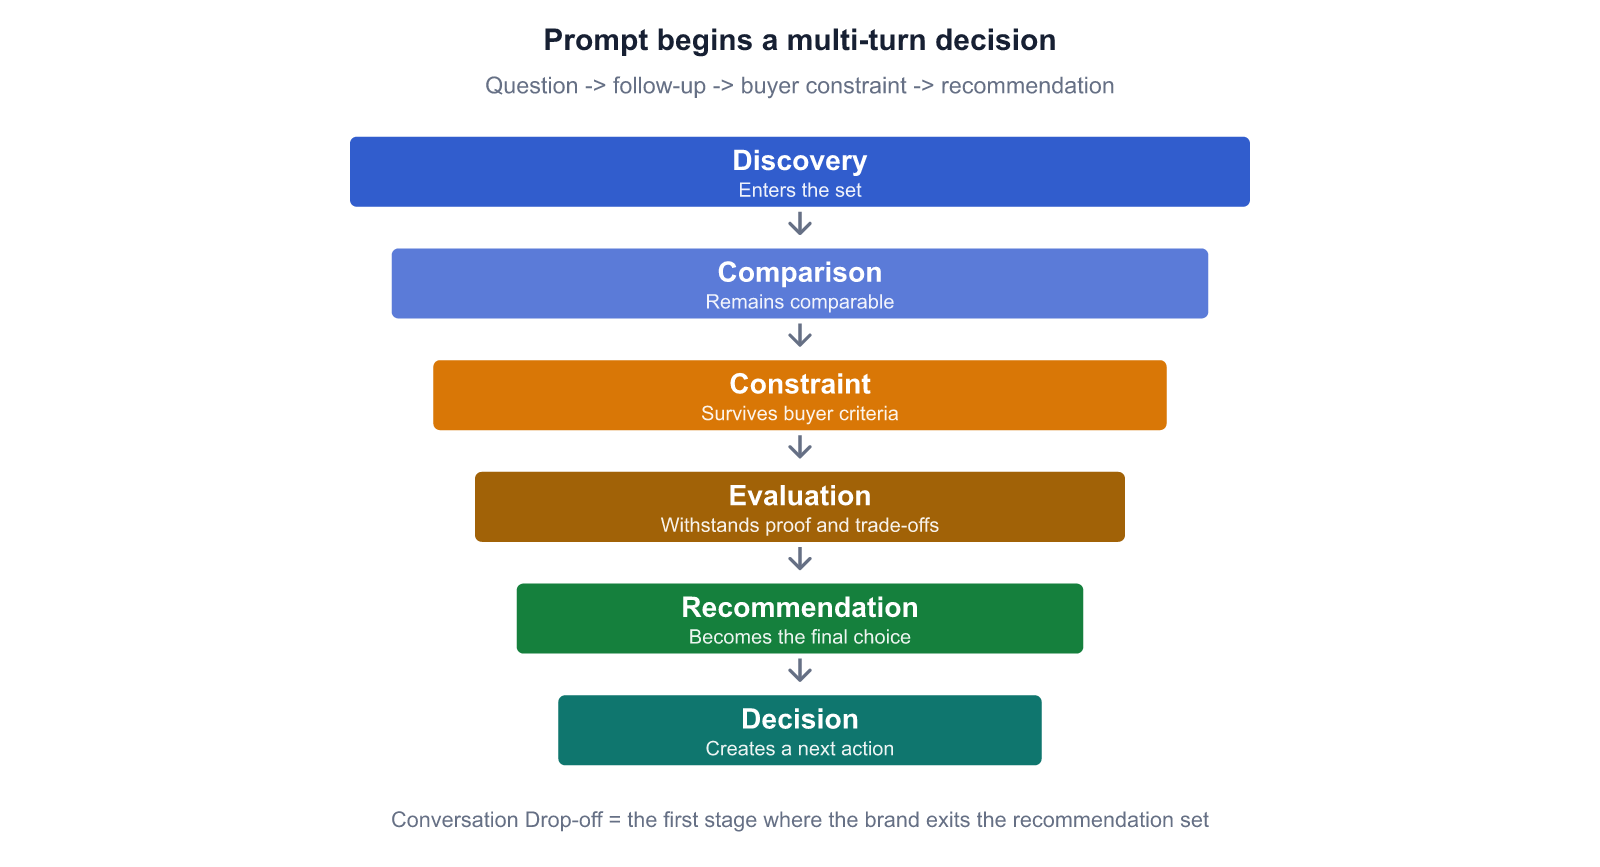
Conversation Analytics: Chat is the new funnel
AEOsim's Conversation Analytics framework measures where brands enter, persist, drop off, and win across multi-turn AI buying conversations.
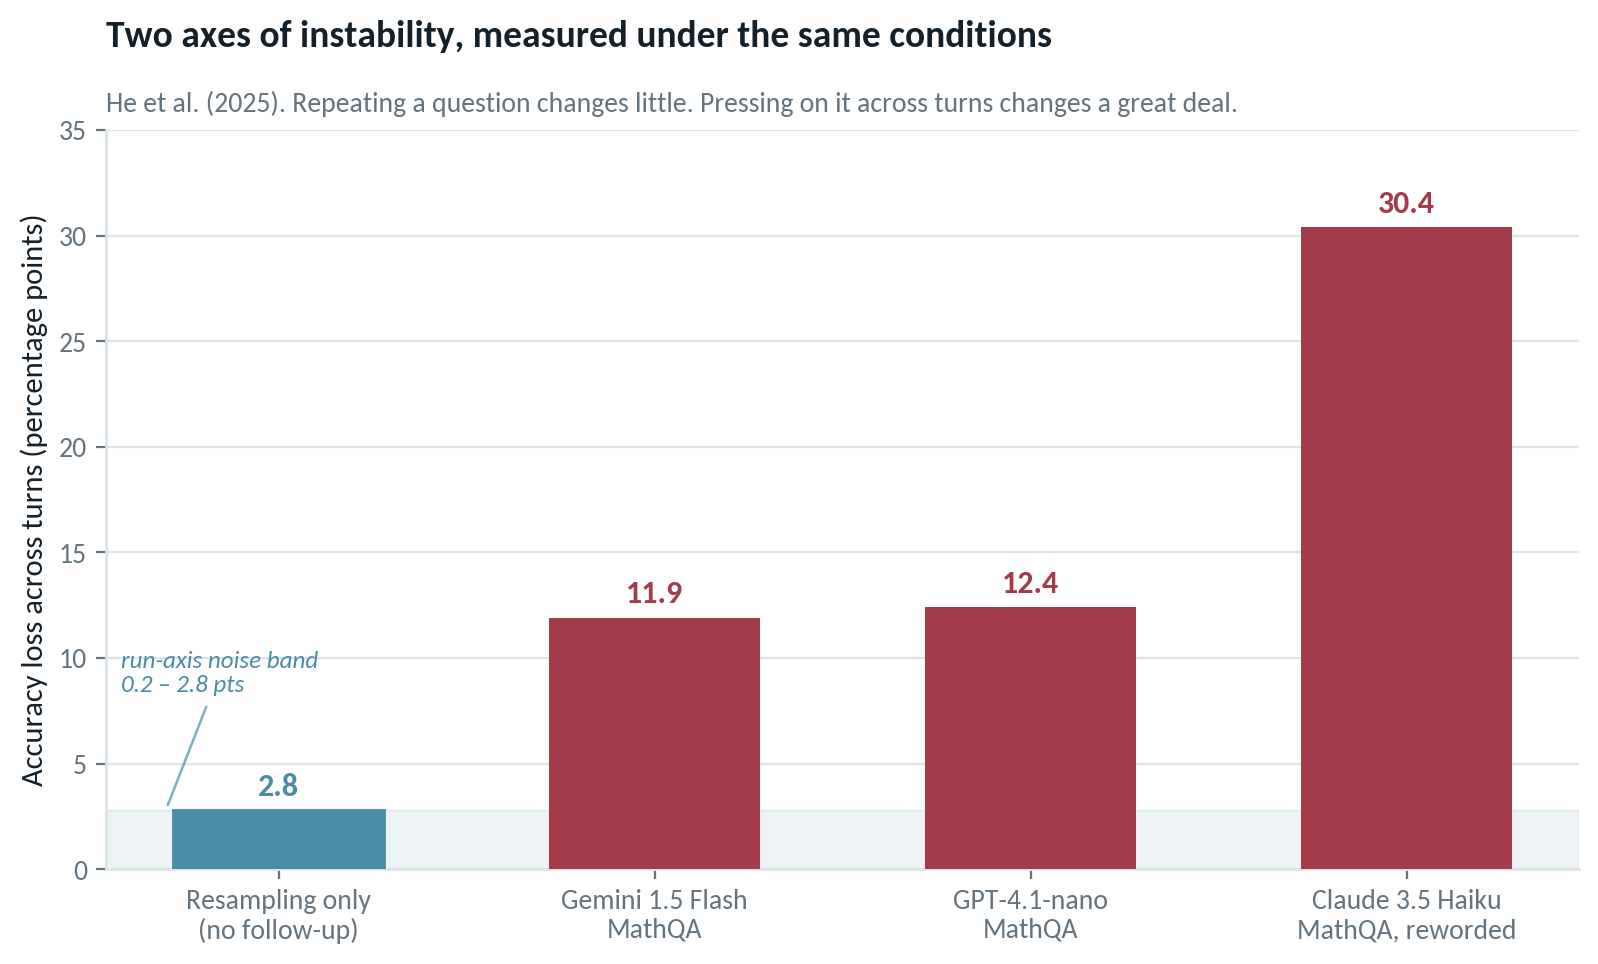
Measuring AI search visibility beyond the first response: A Markov model for brand drop-off, recovery, and half-life across buying turns
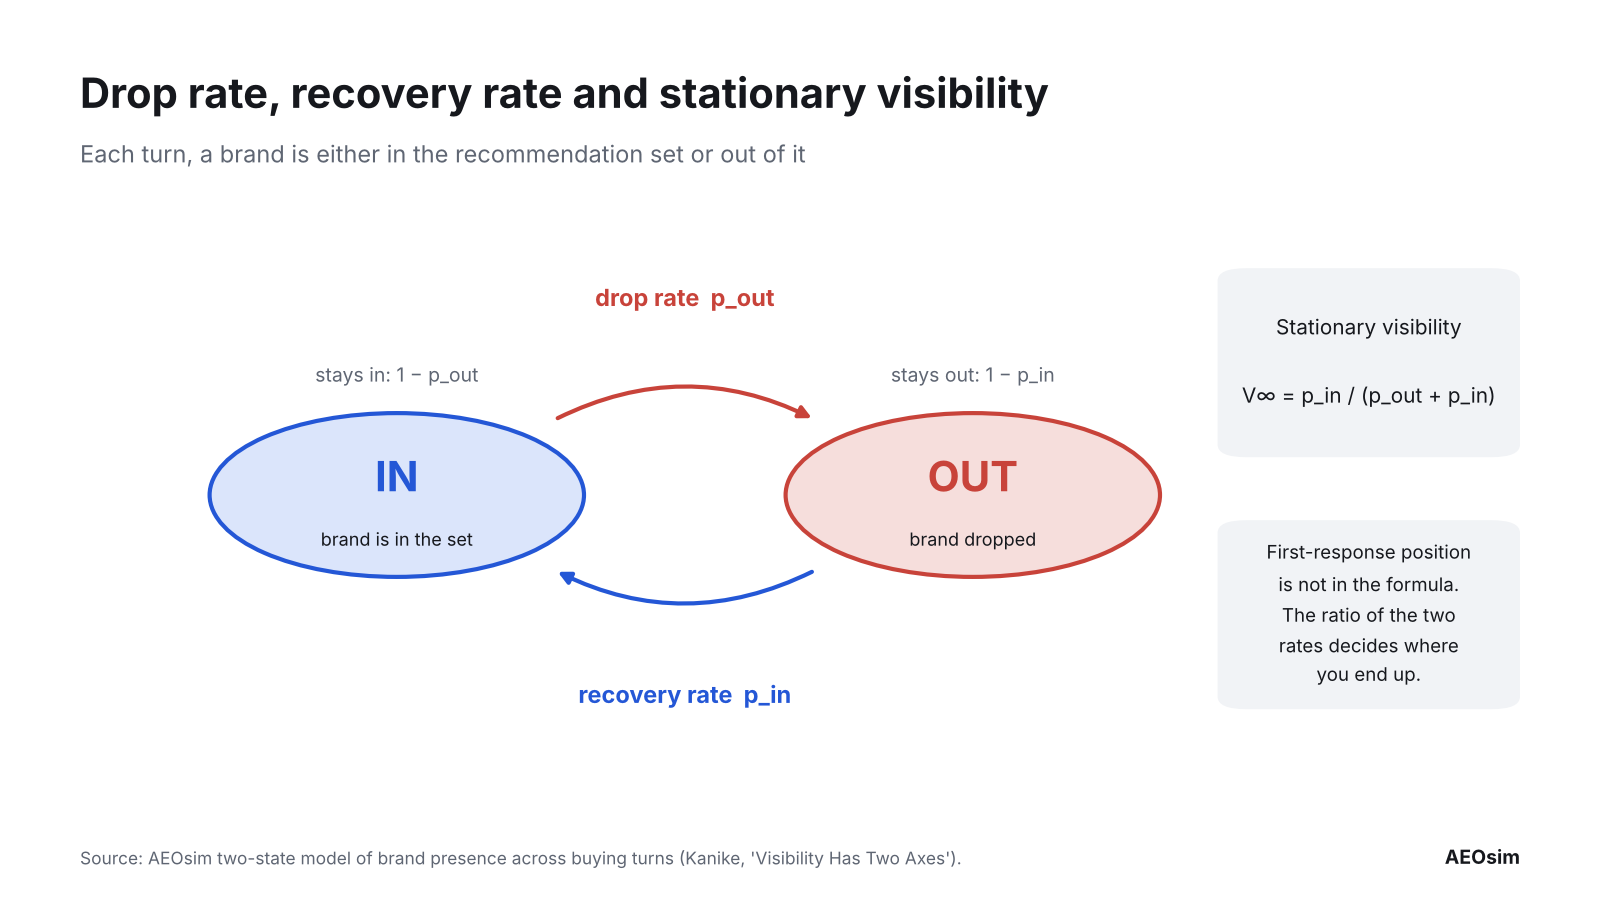
AI visibility research settled on repeated sampling for run-to-run variance. Brand presence also drifts across turns. A two-state Markov chain gives GEO teams drop rate, recovery rate, and visibility half-life.
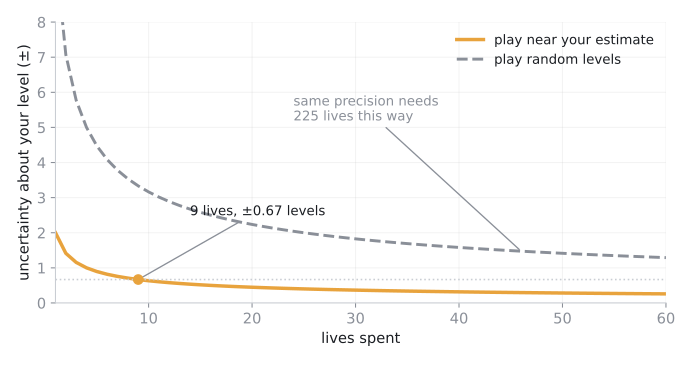
Play the games you might lose: Item information peaks at P=0.5, prompt difficulty, and why always-win dashboards waste compute
Article 4/n on synthetic data in LLM visibility tools. A nine-lives IRT parable: Fisher information I = a²P(1−P), adaptive aiming at the coin-flip band, and why one prompt set cannot inform every brand in a category.
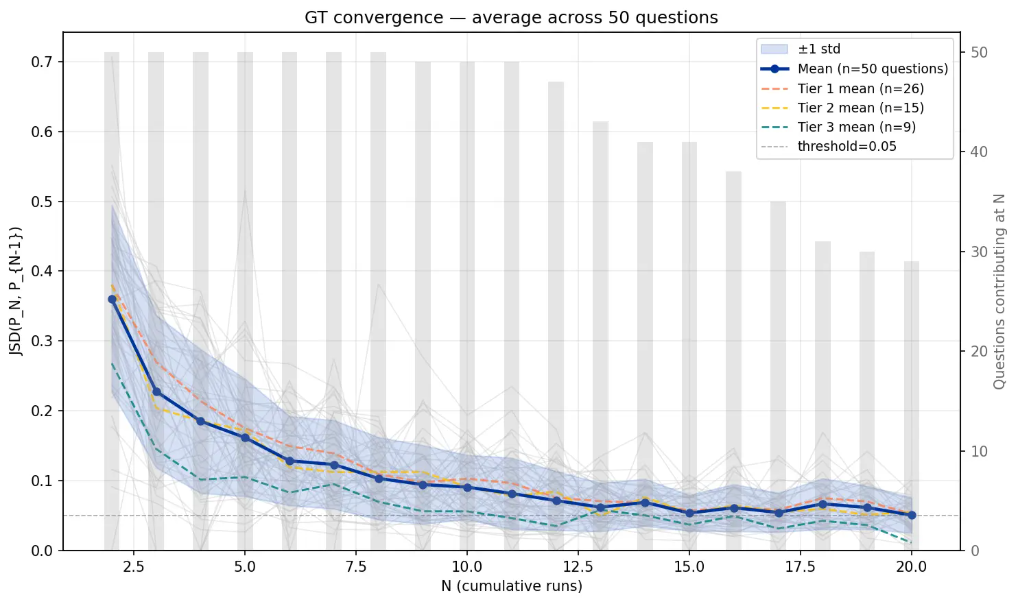
Top 7 AI visibility and AEO/GEO monitoring tools in 2026: A 17-point comparison across measurement integrity, prompt intelligence, setup, and ROI
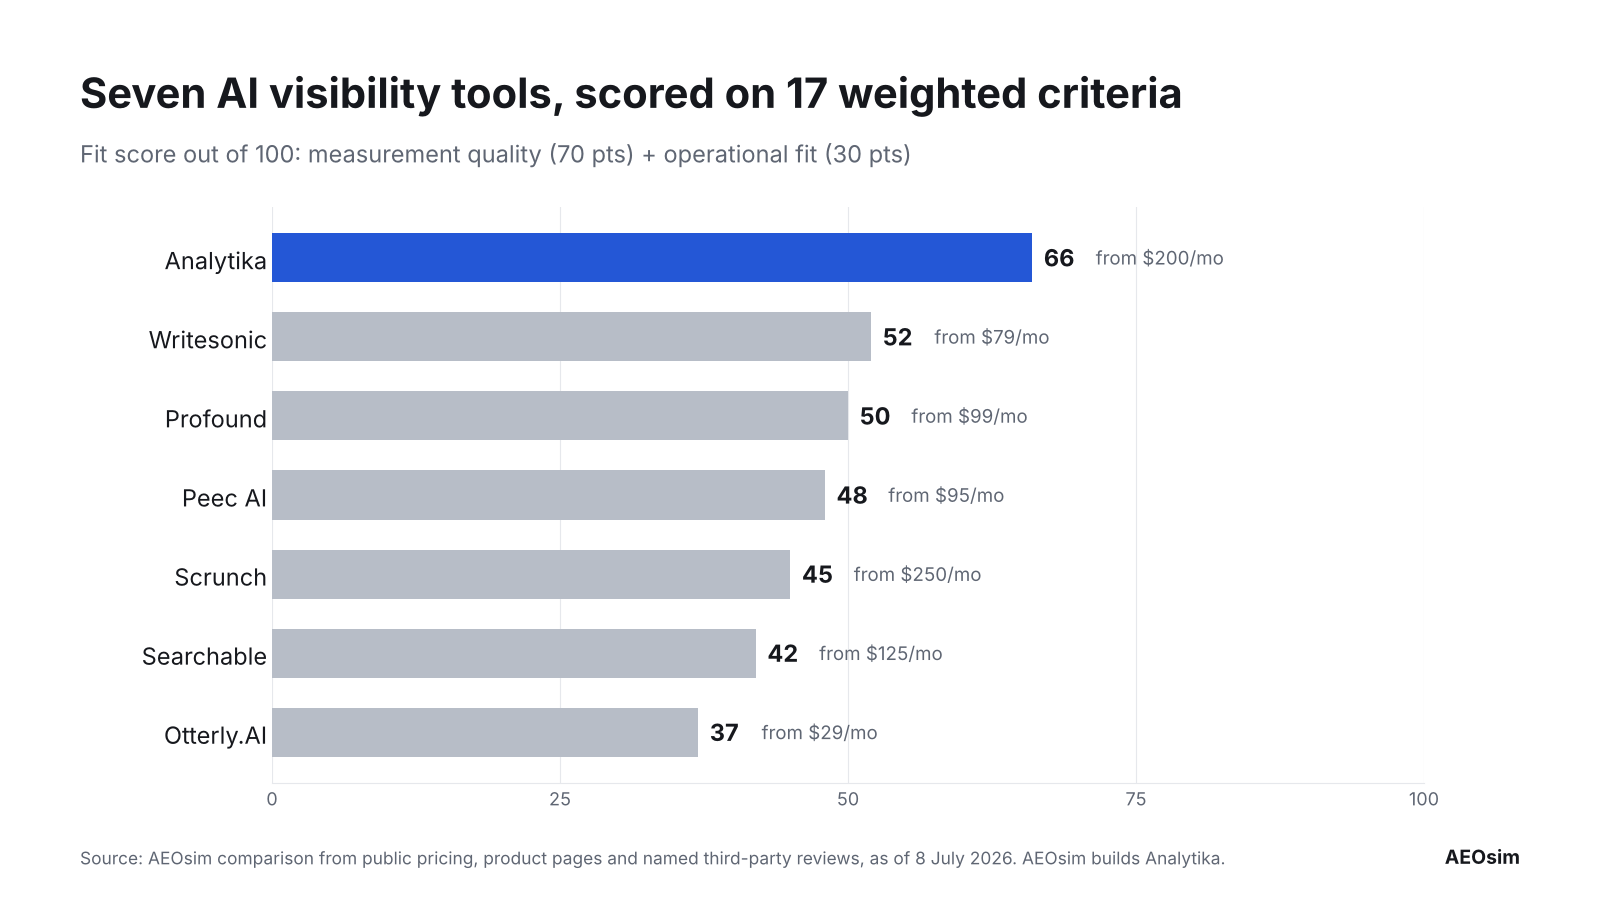
Seven tools scored across 17 weighted criteria. Analytika leads on measurement integrity, with clear guidance on when another tool is the better pick.
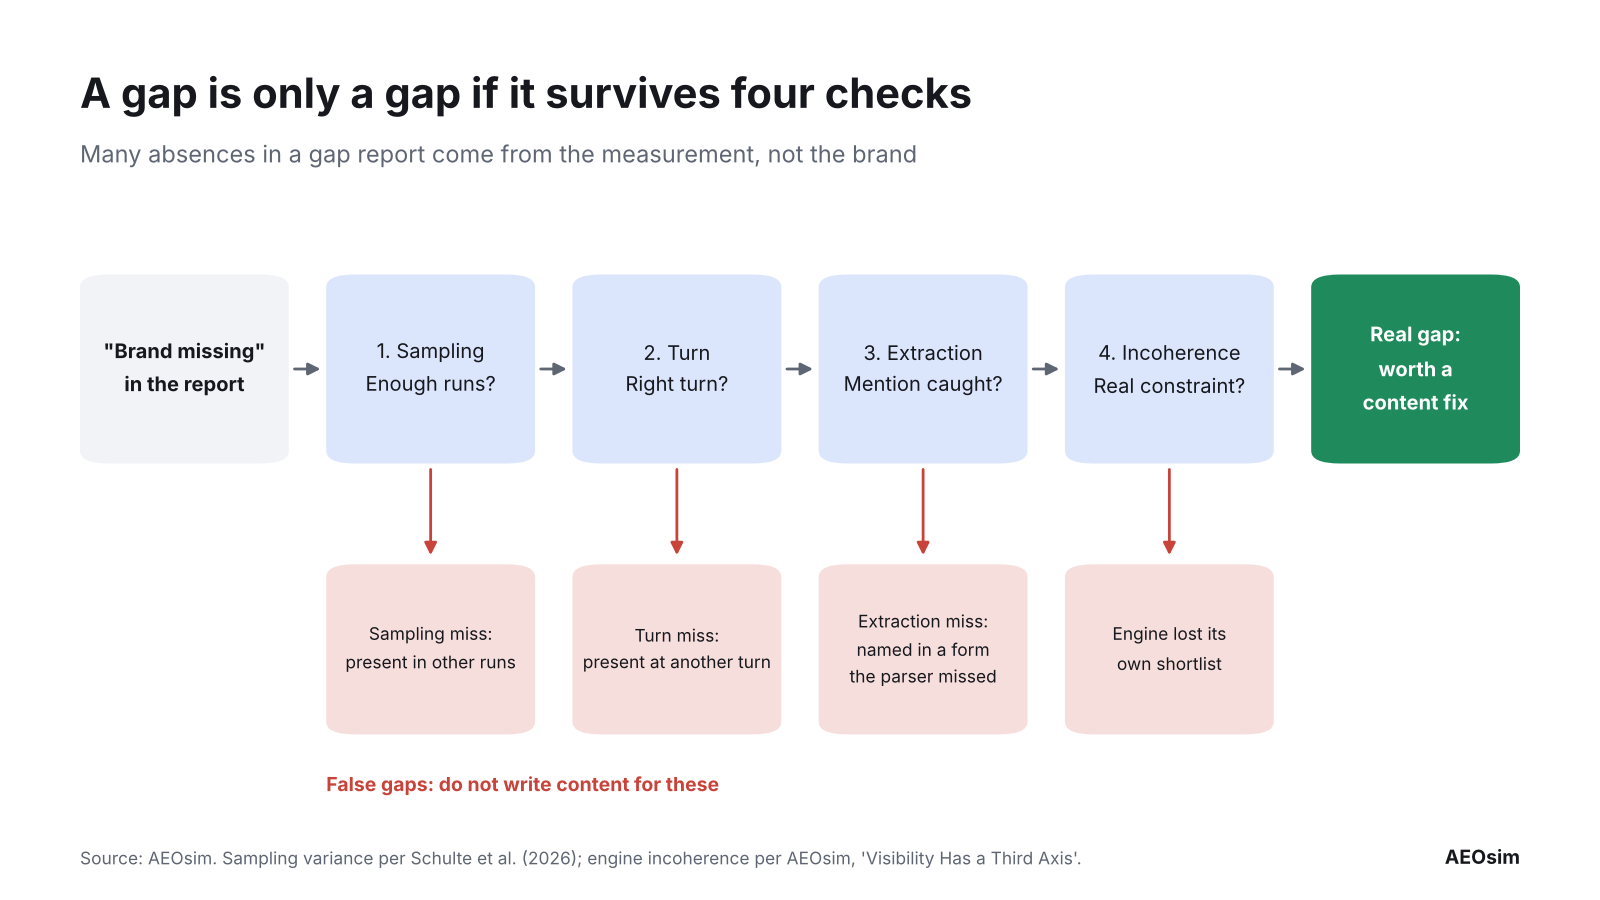
A gap report is only as good as its recall
A gap is an absence, and absence is ambiguous. Sampling misses, turn misses, and extraction misses manufacture gaps. A gap should survive all four checks.
Blogs
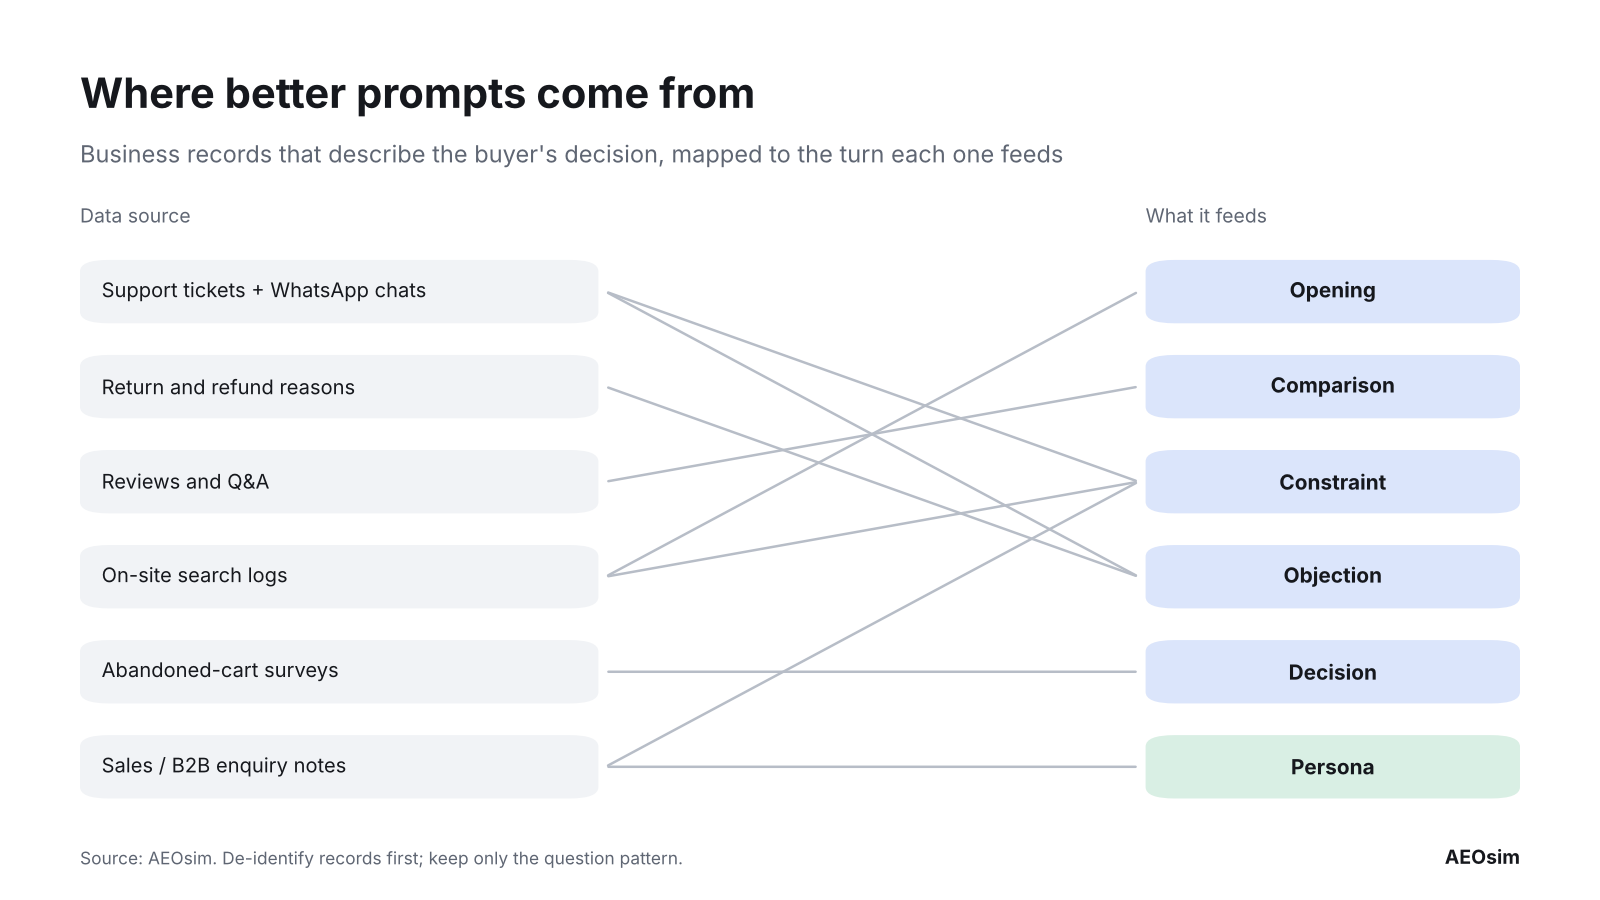
Ground prompts in business data, not GSC keywords
Search Console keywords are real. The questions templated from them are not. Ground prompt sets in support tickets, returns, reviews, and the decisions buyers actually make.
Where your banners sit decides whether AI retrieval finds your product facts: The geometry of page chrome
Page chrome placed above the product facts cuts retrieval of the constraint. With a 512-token window, bge-m3 recall@5 is 0.298 when chrome comes first and 0.845 when it comes last. A retrieval proxy on open models, not a live engine.
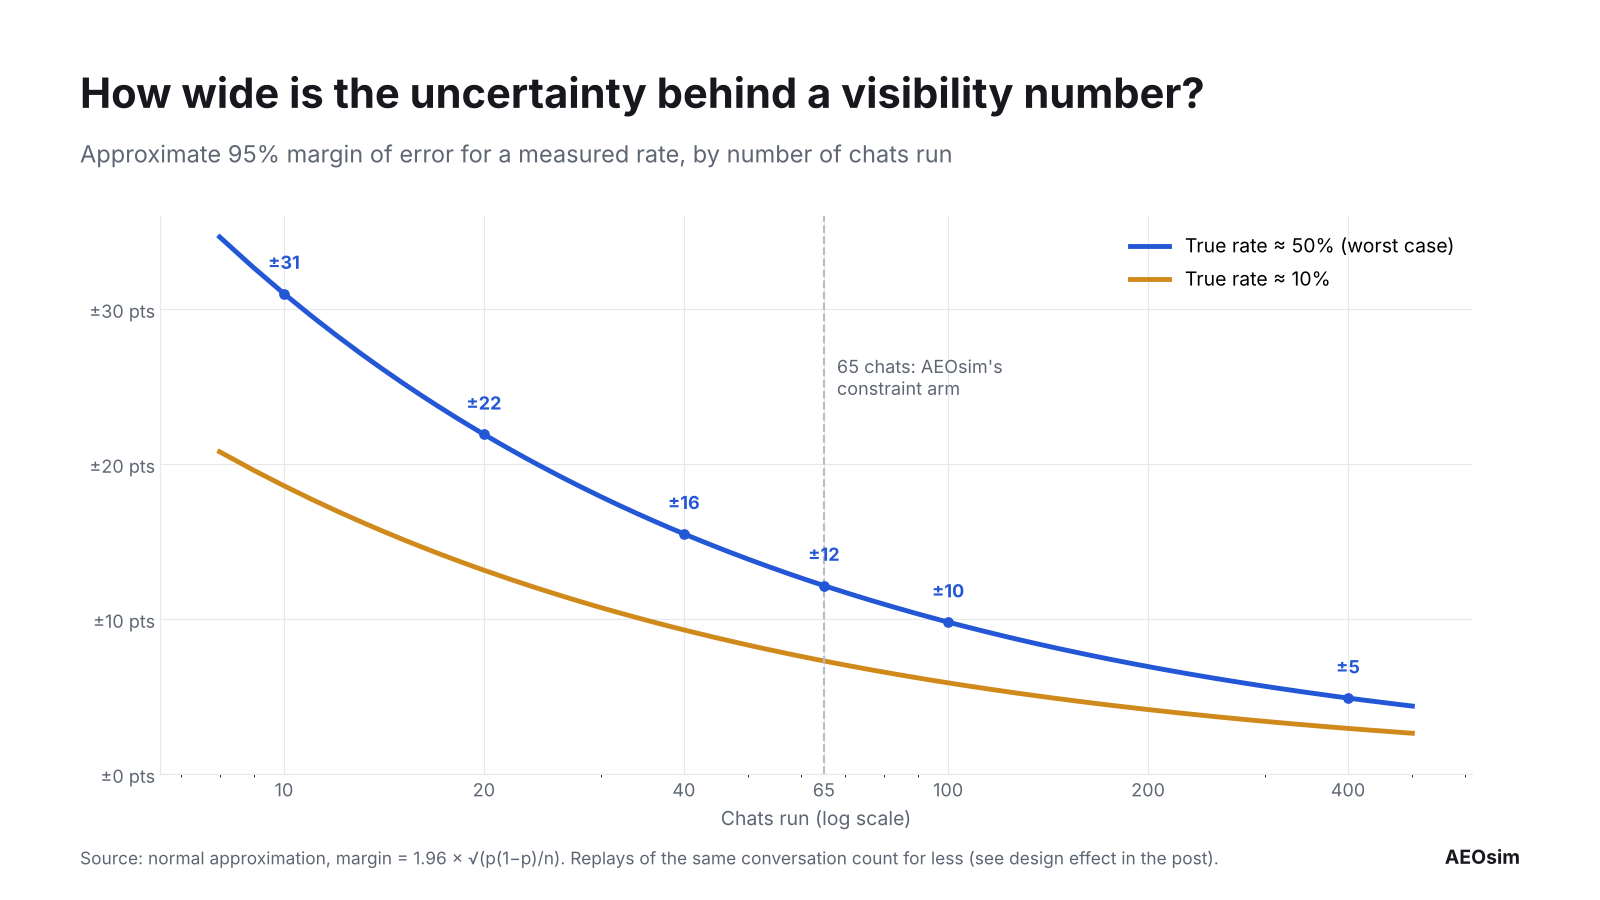
How many chats is enough?
One AI answer is one draw. How sample size, confidence intervals, and replay correlation decide whether a visibility number is a measurement or a screenshot.
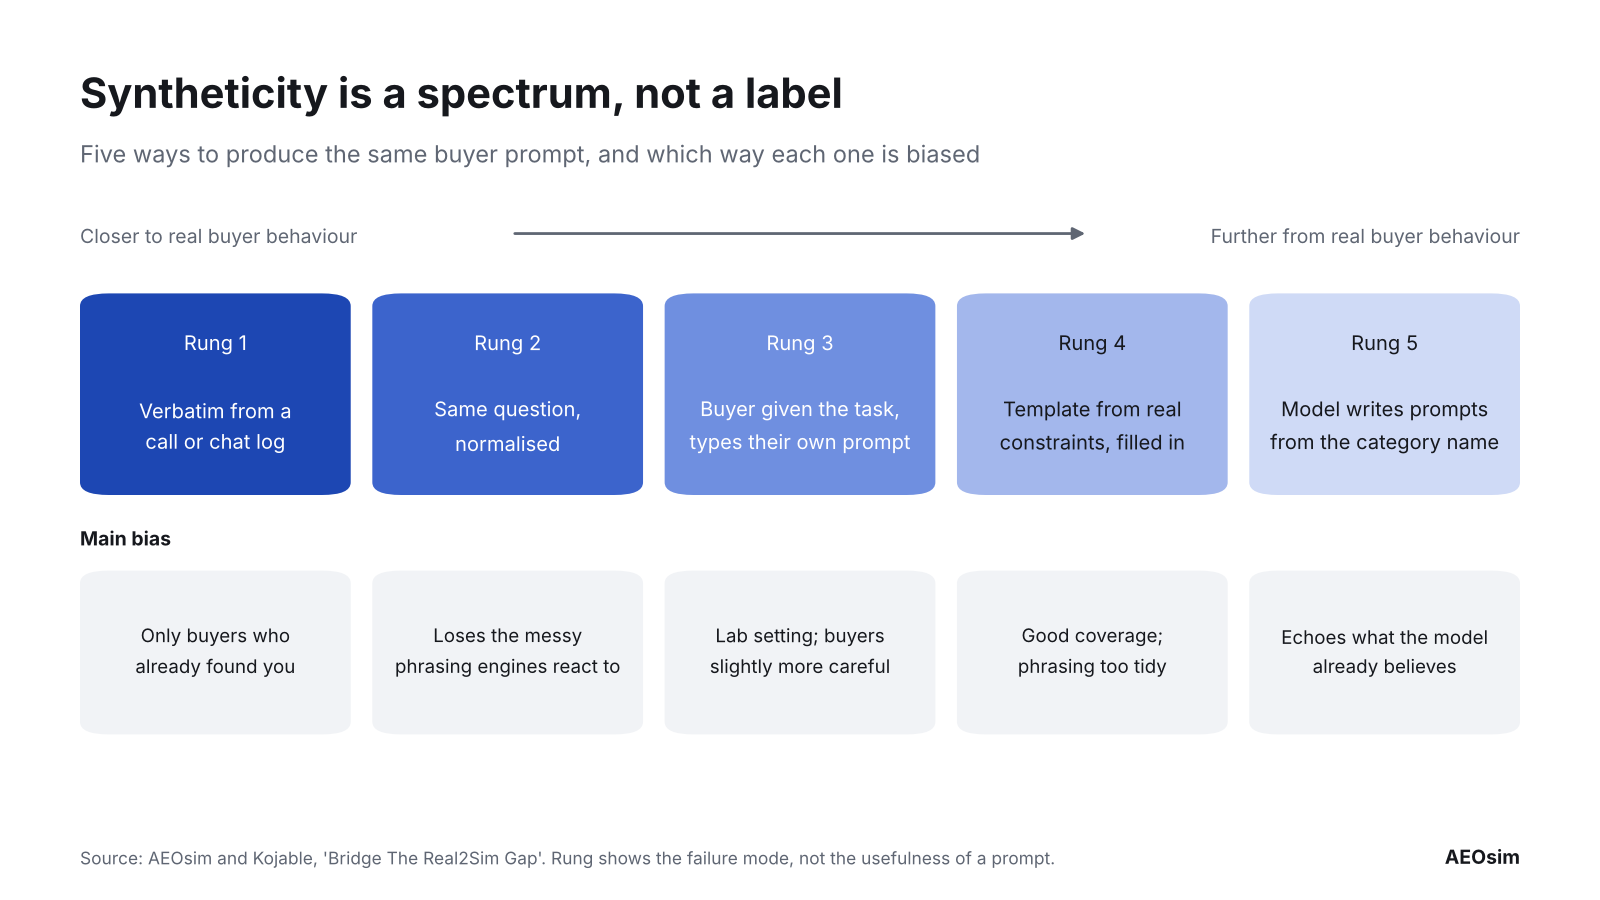
Syntheticity is a spectrum, not a flaw
Real versus synthetic is the wrong split. Every prompt sits on a spectrum, and each rung has a bias that points in a known direction.
Building a prompt set that represents real buyers
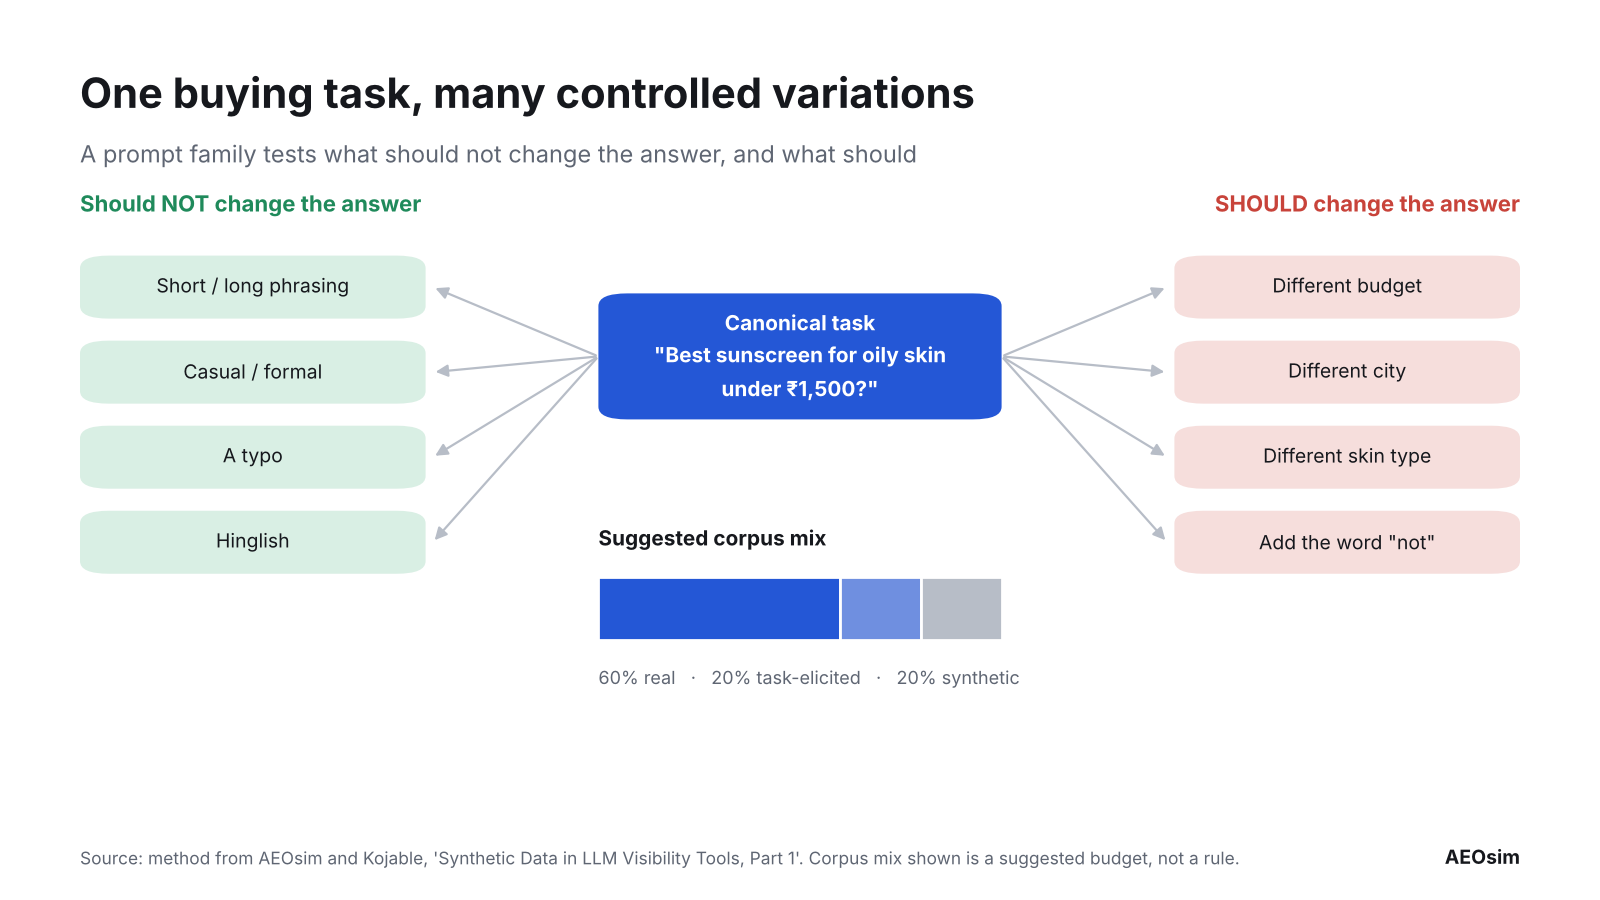
How to build a prompt set that represents real buyers: define the population, script journeys, label sources, and weight prompts by what they are worth.
Multi-turn AEO glossary
Thirty terms for multi-turn AI search, from conversation drop-off and Share of Recommendation to syntheticity, probe surface, and retrieval eligibility.
Inside a free AI-search mini-audit
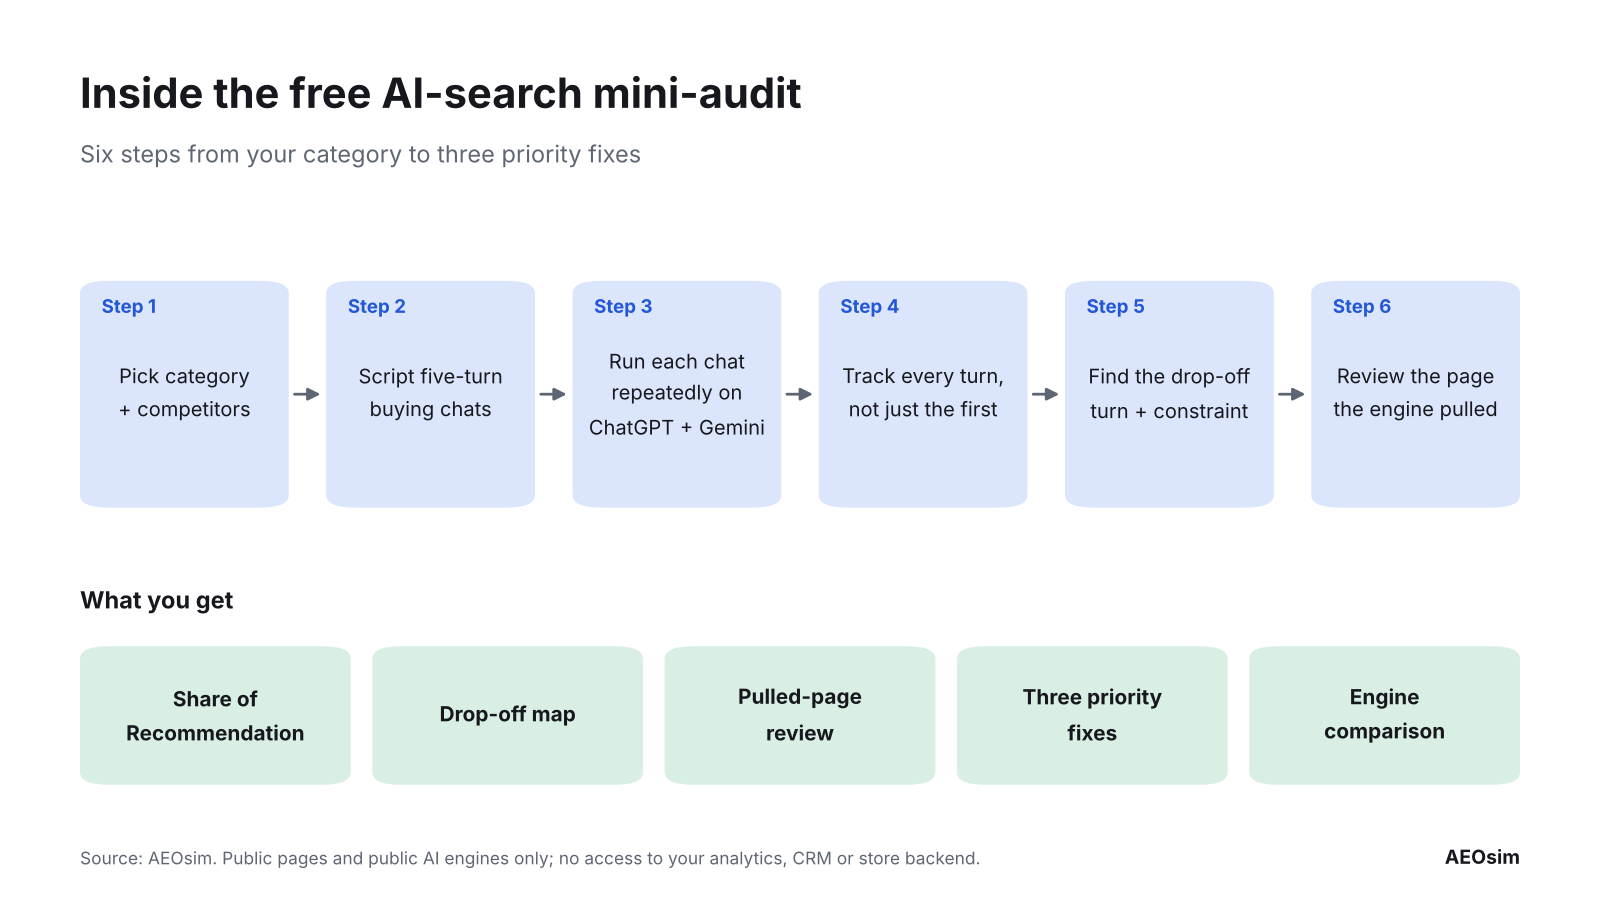
What the free mini-audit checks for one category: whether your brand survives to the final recommendation, where it drops, and which page the engine pulled.
Why AI visibility tools disagree (extended)
Three tools, three scores. Disagreement comes from five quiet choices: surface, prompts, runs, turn, and retrieval. Eight checks to run before you trust any dashboard.
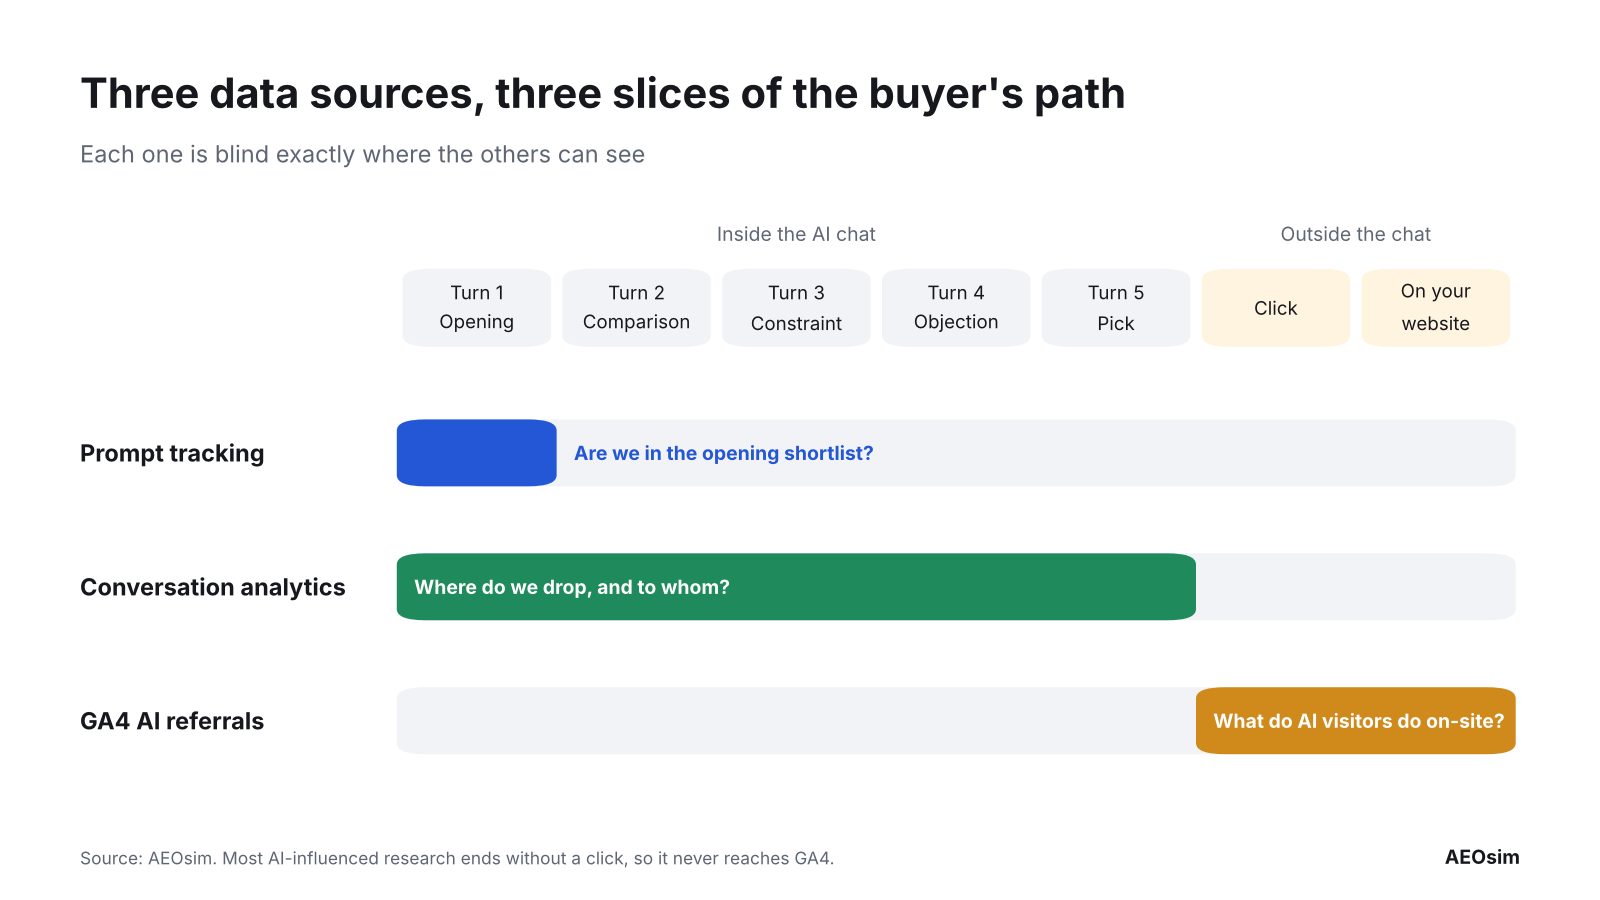
Conversation analytics vs prompt tracking vs GA4 referrals
Prompt tracking, conversation analytics, and GA4 AI referrals each see a different slice of the buyer's path. Using one to answer another's question is how teams misread AI search.
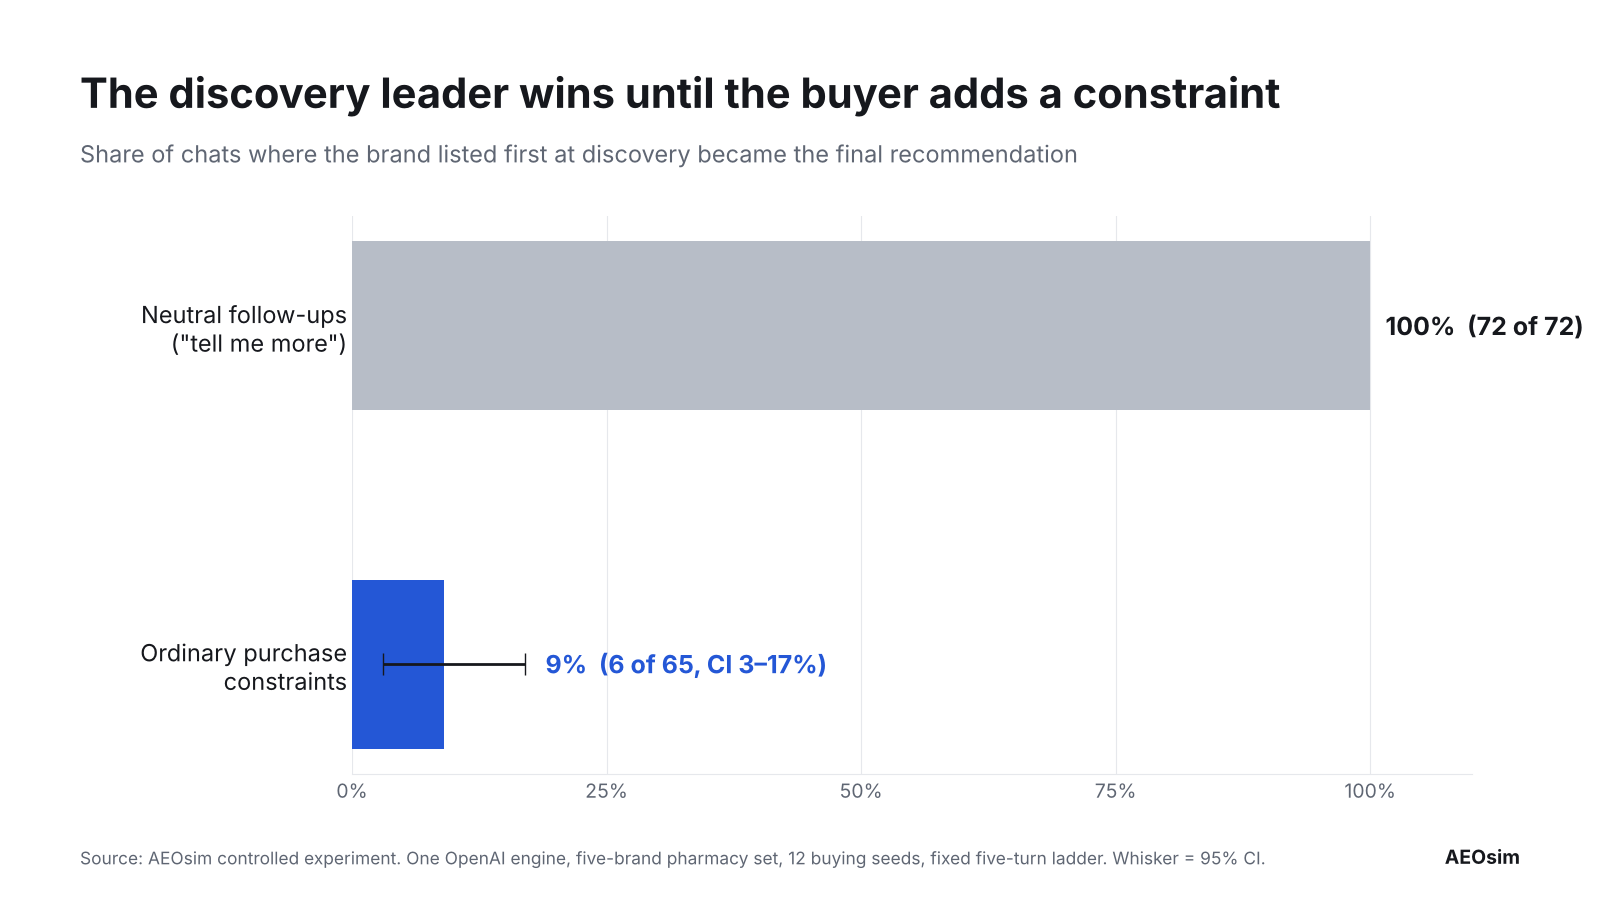
Chat is the new funnel: The complete guide to multi-turn AI search for ecommerce
A guide to multi-turn AI search for ecommerce: where a brand enters, drops, and wins a buying chat, and what the product page has to do at the decision turn.
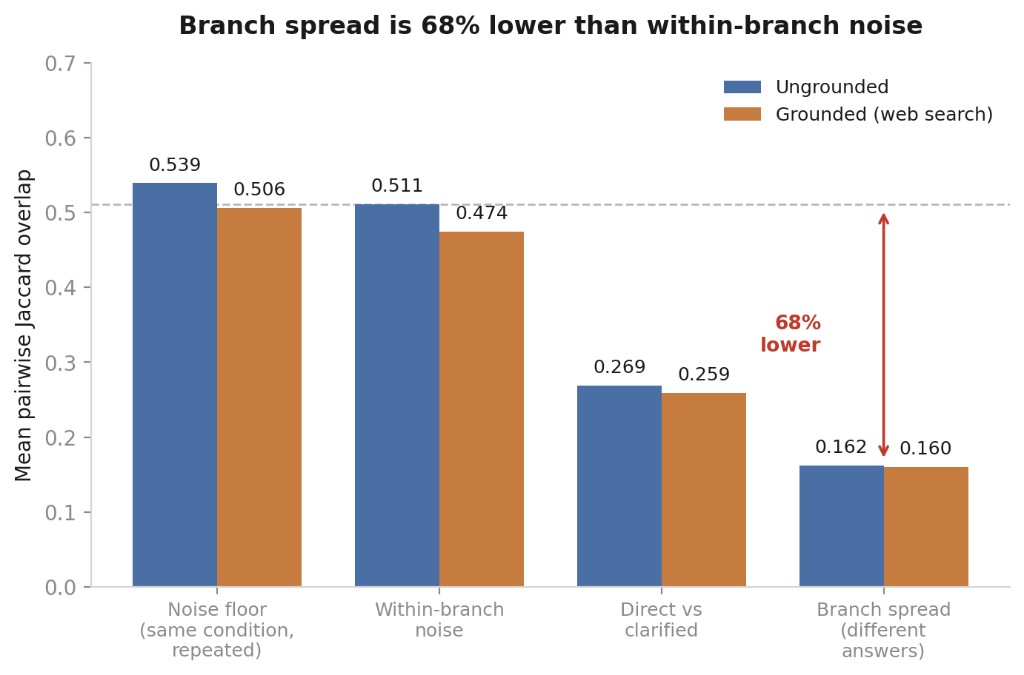
Clarification as a branch point in AI recommendations: Alternative clarifying answers cut brand-set Jaccard overlap 68% below within-branch noise
Twelve commercial categories on GPT-5.6 Luna: branch spread Jaccard 0.162 vs within-branch noise 0.511 ungrounded (68% lower), 12/12 positive paired gaps, and web_search left the effect intact.
AI answer alignment beyond factual accuracy: Six observation dimensions, materiality and recurrence gates, and misalignment rates across prompt families
Article 3/n on synthetic data in LLM visibility tools. Score six answer observations per run, gate on materiality and recurrence, and read misalignment as a rate by family, engine, and multi-turn trajectory.
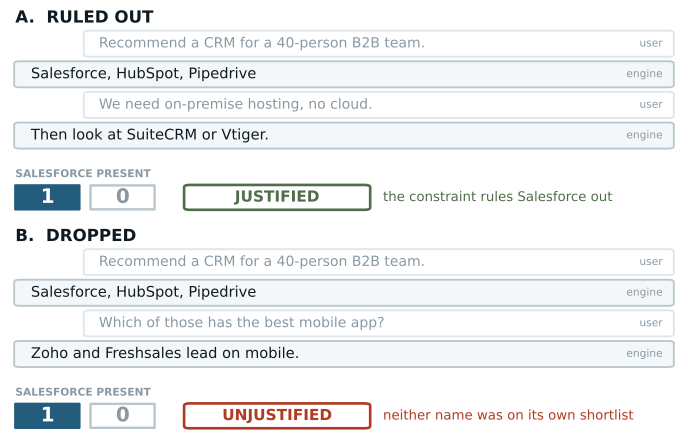
Visibility has a third axis: Separating brand exclusion from engine incoherence in multi-turn drop rates and half-life
Your drop rate is measuring two different things at once. Coherence separates justified brand exclusion from engine forgetfulness, and γ can reverse cross-engine rankings.
Top AEO/GEO experts to follow in 2026
Five 2026 AI search and GEO practitioners selected for original research, shipped tooling, and technical frameworks, plus how the cohort was scored, and where legacy SEO and academic GEO fit.
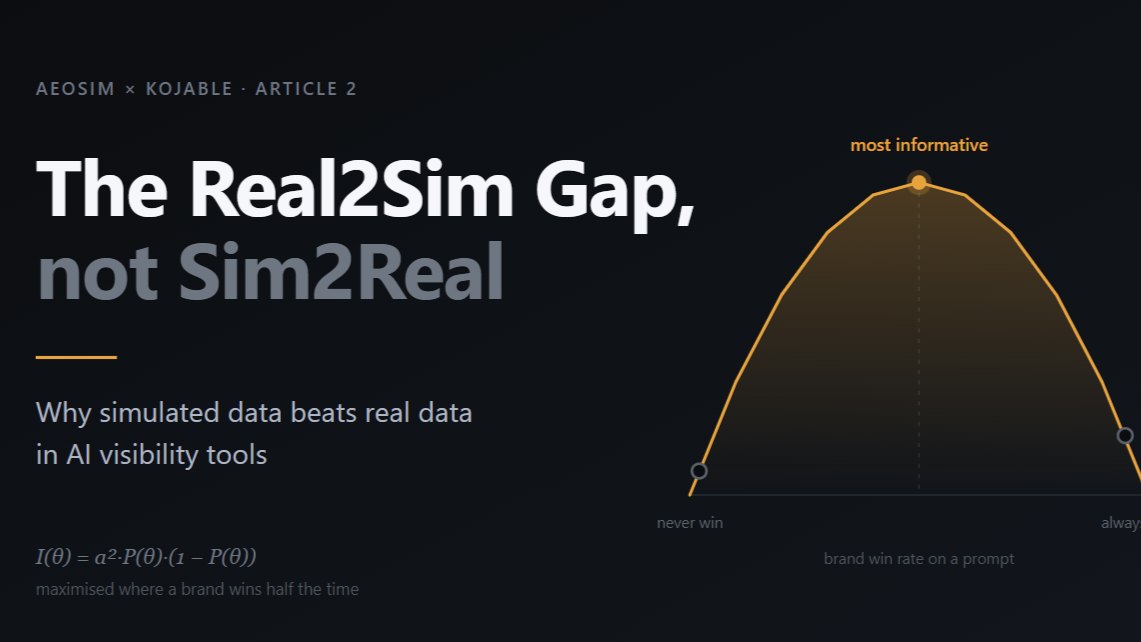
Bridge the Real2Sim gap, not Sim2Real: Why simulated data beats real data in AI visibility tools
If the prompts are made up, what is the measurement worth? Often more than the real alternative. Item response theory, information peaks at P=0.5, and what simulation can do that observation cannot.
Synthetic data in LLM visibility tools, part 1: How we build the prompt set
How to build an intentional, auditable prompt corpus for LLM visibility evaluation: variation types, 60/20/20 mix, syntheticity as a spectrum, and grounding when there is no AI query log.
The retrieval gate: When AI search actually cites Reddit
A Monte Carlo study of when a search-augmented model cites reddit.com, and why optimizing for Reddit aims at a door the model rarely opens.
How much should you care about AI search: An industry-specific guide
Buyer research is moving into ChatGPT, Gemini, and Perplexity before the click. Most analytics stacks never see it. This piece covers the cost and how to measure it.
2 reasons why the rich get richer in LLM citations
Two mechanisms compound citation bias in LLMs: a parametric popularity prior in the weights, and an inference-time incentive to treat reputation as a cheap evaluation shortcut. Implications for AEO and GEO.